
Flux Kontext Max image-to-image
Model Overview
An image-to-image model that modifies only what the prompt instructs, leaving the rest of the image untouched.
flux/kontext-max/image-to-image
Format: JPEG, PNG Image size can't be set directly — only a preset aspect ratio can be chosen. Default aspect ratio and size: 16:9, 1184x880 (well, not quite 16:9)
Setup your API Key
If you don’t have an API key for the AI/ML API yet, feel free to use our Quickstart guide.
API Schema
The text prompt describing the content, style, or composition of the image to be generated.
Number of image variations to generate. Each image is a different attempt to combine the reference images (from the image_url parameter) according to the prompt.
1The same seed and the same prompt given to the same version of the model will output the same image every time.
The CFG (Classifier Free Guidance) scale is a measure of how close you want the model to stick to your prompt when looking for a related image to show you.
The safety tolerance level for the generated image. 1 being the most strict and 5 being the most permissive.
2Possible values: The format of the generated image.
jpegPossible values: The aspect ratio of the generated image.
16:9Possible values: One or more image URLs used as visual references. The model merges them into a single image following the prompt instructions.
curl -L \
  --request POST \
  --url 'https://api.aimlapi.com/v1/images/generations' \
  --header 'Authorization: Bearer <YOUR_AIMLAPI_KEY>' \
  --header 'Content-Type: application/json' \
  --data '{
      "model": "flux/kontext-max/image-to-image",
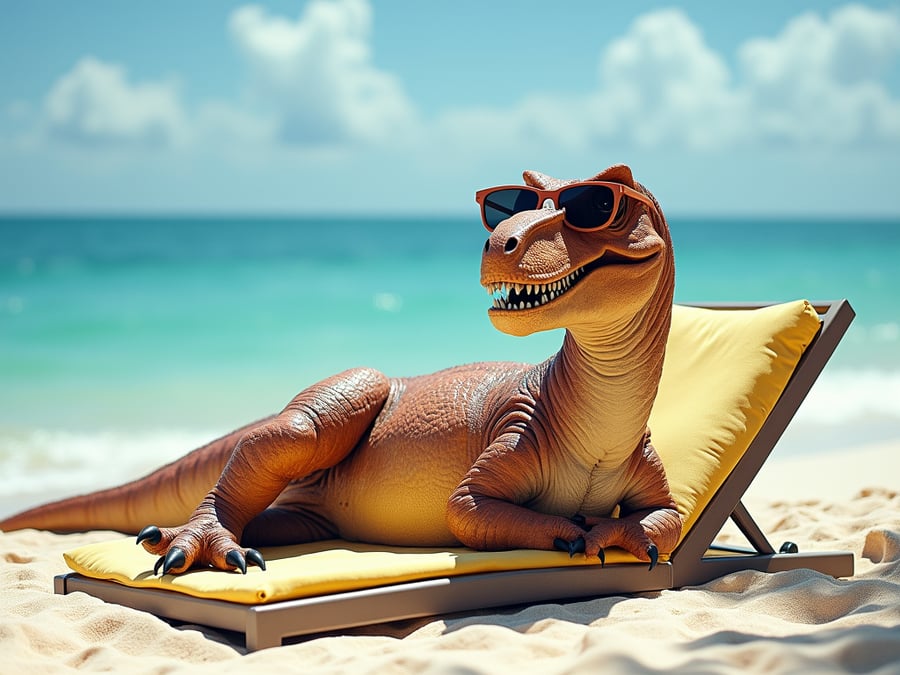
      "prompt": "Add a crown to the T-rex’s head.",
      "image_url": "https://raw.githubusercontent.com/aimlapi/api-docs/main/reference-files/t-rex.png"
}'{
"data": [
{
"url": "https://cdn.aimlapi.com/generations/hedgehog/1749730923700-29fe35d2-4aef-4bc5-a911-6c39884d16a8.png",
"b64_json": null
}
],
"meta": {
"usage": {
"credits_used": 120000
}
}
}Quick Example
Let's generate a new image using the one from the flux/dev Quick Example as a reference — and make a simple change to it with a prompt.


Example #2: Combine two images
This time, we’ll pass two images to the model: our dinosaur and a solid blue mug. We'll ask the model to place the dinosaur onto the mug as a print.
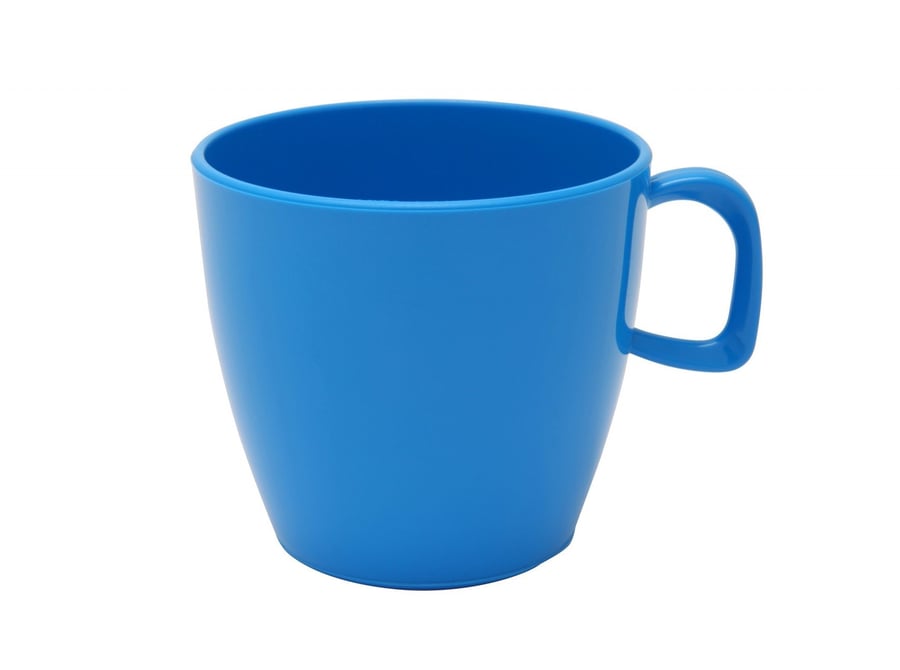

"Place this image with the t-rex on this mug from the second image as a print. Make it look fit and natural."Last updated
Was this helpful?